One-step Generation in the Post Diffusion Era
Training-based routes toward one-step generation for diffusion and flow models, covering distillation, Consistency Models, CTM, MeanFlow, DMD, and Drifting Models.
 Slides PDF Open slides ↗
Overview#
Diffusion models are still one of the major paradigms in image and video generation. They produce high-quality samples and remain a strong default for many generative tasks. However, their sampling process is inherently iterative: generation usually requires many denoising steps or numerical solver evaluations. This inference-time iteration becomes a practical bottleneck when we care about fast generation, large-scale serving, or long-form generation.
This post gives a high-level review of training-based approaches toward one-step or few-step generation: methods that try to compress, replace, or bypass the inference-time trajectory through distillation, consistency constraints, average-velocity regression, distribution matching, or training-time distribution evolution.
Drifting Models are discussed in more detail than the others because they make this contrast especially explicit. Diffusion and flow models evolve samples during inference, while Drifting Models interpret training itself as a distribution-evolution process: as the generator parameters change, the generated distribution drifts toward the data distribution. The purpose of the post is still broader than Drifting Models alone: to organize several attempts at one-step generation and clarify what each method depends on.
Generative Modeling#
Pushforward Formulation#
At a high level, generative modeling can be written as a pushforward problem. We start from a simple prior distribution, such as a Gaussian noise distribution
Diffusion / Flow Models: Inference-Time Iteration#
Diffusion and flow models make the pushforward problem tractable by decomposing a complex transformation into many small steps. Instead of learning the full noise-to-data map in one shot, they introduce an intermediate time variable and learn a score, denoising direction, or velocity field that tells each sample which direction to move along the trajectory.
In both cases, sampling can be viewed as solving learned SDE or ODE dynamics that move each sample from noise toward data at inference time. Numerically solving these dynamics requires iterative updates. This multi-step inference-time sampling is the bottleneck that motivates one-step generation.
Training-Based Attempts Toward One-Step Generation#
This section reviews training-based attempts to obtain one-step or few-step generators. The methods differ mainly in what training signal they use: teacher trajectories, trajectory consistency, average velocity, score-based distribution matching, or training-time distribution evolution.
Progressive Distillation#
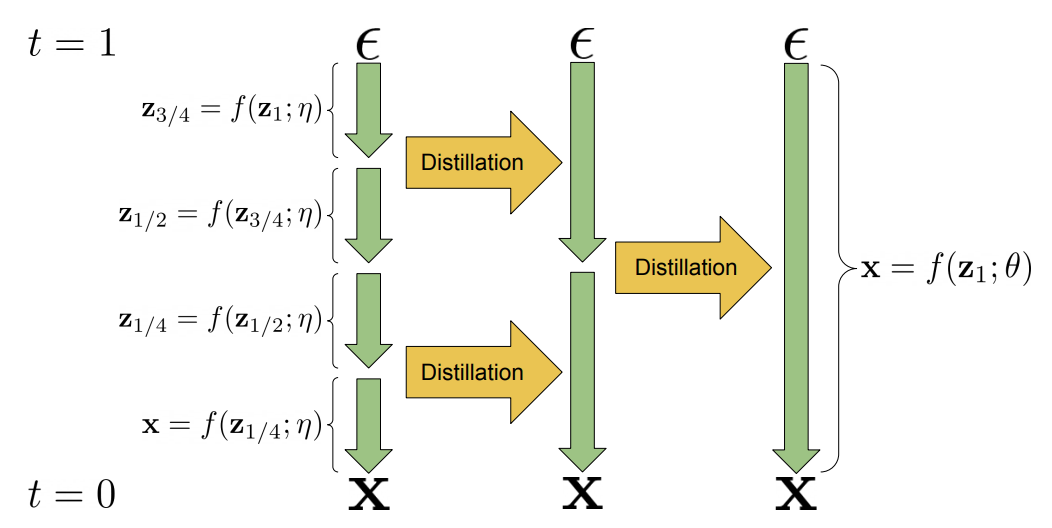
Progressive distillation trains a student one-step transition to match two consecutive teacher transitions:
Consistency Models#
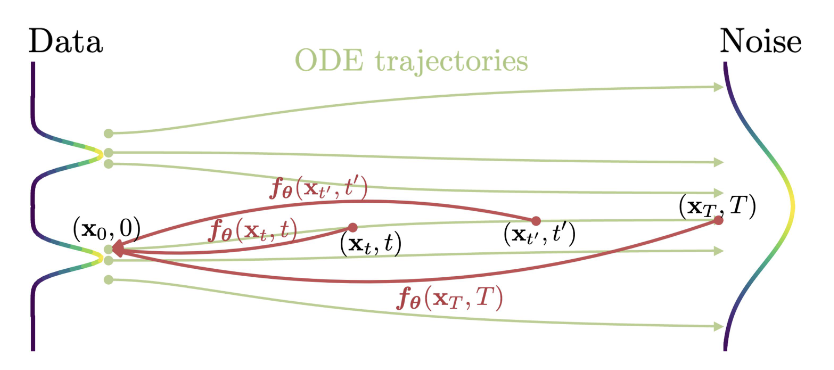
The key idea of Consistency Models is to learn a function whose output is consistent along the same probability-flow ODE trajectory. Instead of predicting only the next denoising step, the model maps noisy samples at different times to the same clean endpoint.
The consistency constraint is:
The practical question is how to obtain such paired points. Consistency Models use two main training setups: Consistency Distillation (CD) and Consistency Training (CT). The pair construction differs as follows:
CD uses a pretrained score model
After training, one-step sampling is a single evaluation from terminal noise:
Limitation#
-
Unstable training. Consistency Models are highly sensitive to curriculum design, such as how the time discretization is scheduled and how difficult trajectory pairs are introduced during training.
-
Indirect training signal. The constraint
-
Dependence on diffusion teacher in CD. Consistency distillation still requires a pretrained diffusion or score model to construct reliable same-trajectory pairs.
CTM#
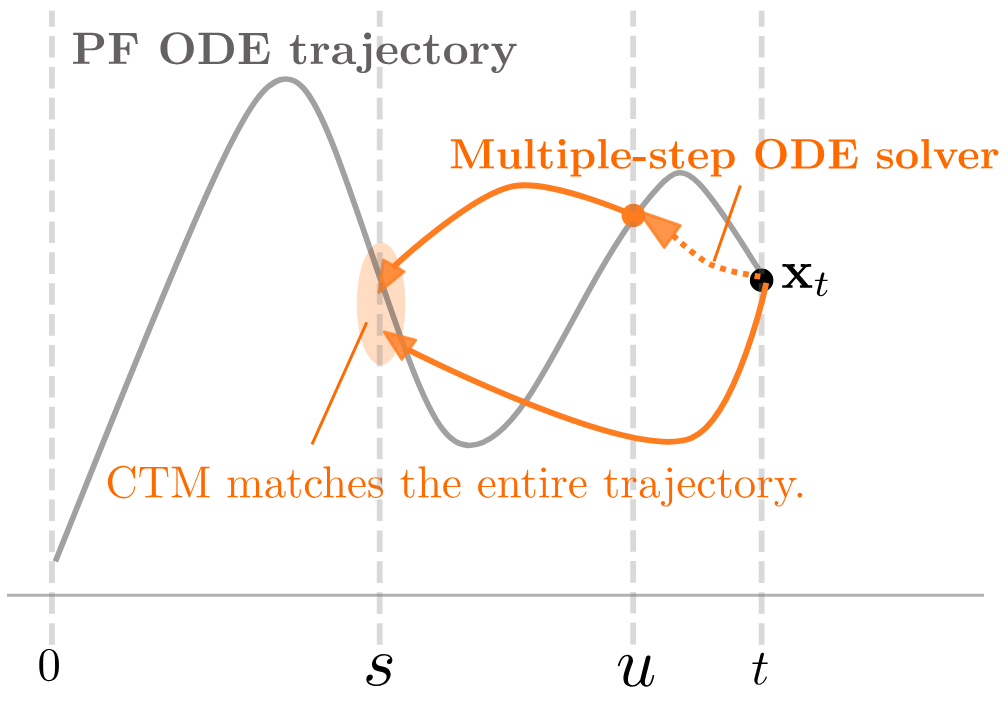
Consistency Trajectory Models (CTM) extend Consistency Models from endpoint consistency to trajectory consistency. Instead of only mapping a noisy point to the clean endpoint, CTM learns a transition map
that moves a sample from time
The trajectory consistency constraint is:
That is, a direct jump from
CTM also has to handle special cases of the transition map. For example,
After training, one-step sampling is:
Because the target time
Limitation#
-
Additional constraints for special cases. CTM is more flexible than CM because it models transitions between arbitrary times, but that flexibility introduces boundary cases such as
-
Training stability. CTM still has an indirect training signal: the model is trained by making direct and composed paths agree, unlike MeanFlow’s velocity-regression-style objective.
-
Not self-contained. Strong practical performance requires an additional GAN component.
MeanFlow#
The key idea of MeanFlow is to learn the average displacement over a time interval, rather than the instantaneous velocity at each time. Flow Matching learns a local velocity field
The average velocity is defined as:
The training signal comes from the MeanFlow identity, which connects this average velocity to the instantaneous velocity:
The derivative term is computed with a Jacobian-vector product (JVP), so the method can train the average-velocity model with a regression-style objective rather than a trajectory-consistency constraint.
After training, one-step sampling applies the learned average displacement over the full interval:
Limitation#
- Additional constraint for the special case. When the interval collapses, MeanFlow needs the average velocity to match the instantaneous velocity:
DMD#
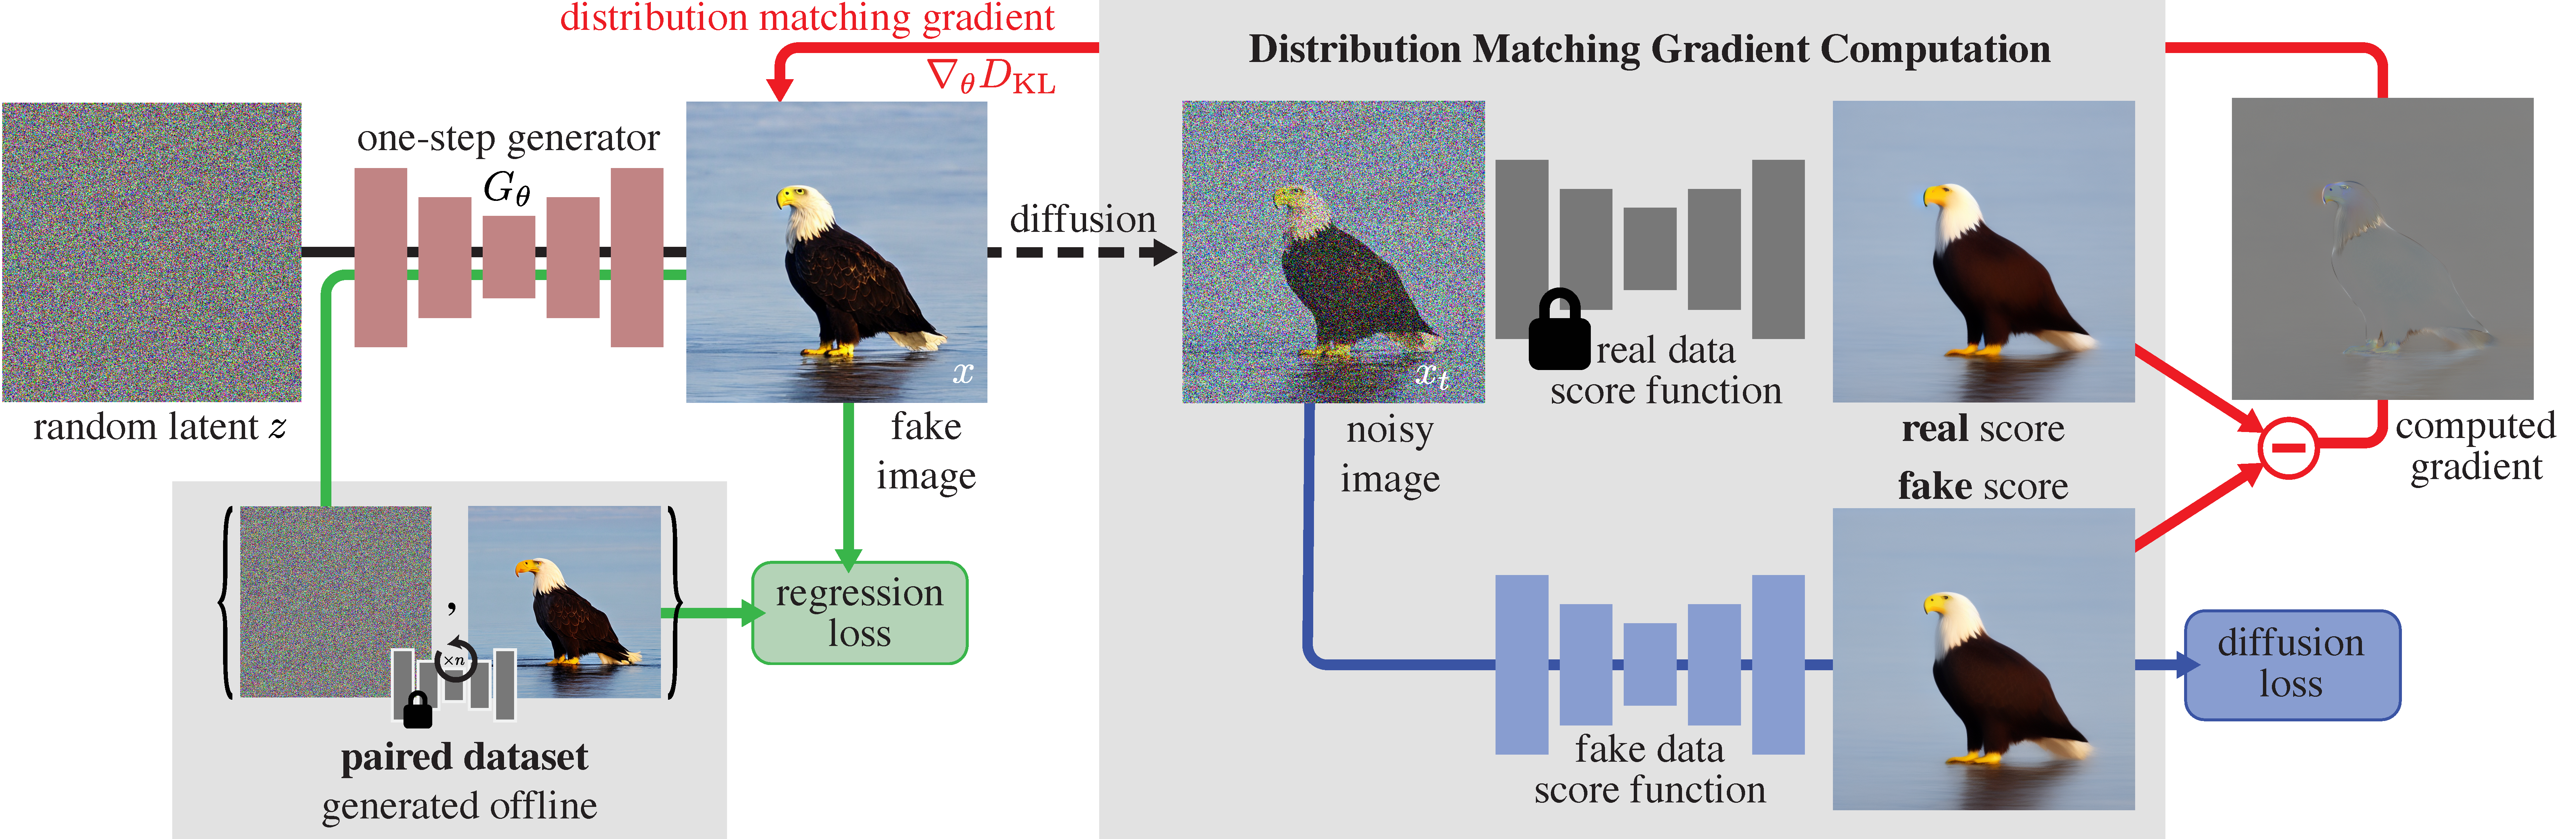
The key idea of Distribution Matching Distillation (DMD) is to train a one-step generator by directly matching the generated distribution to the data distribution. Instead of enforcing agreement along an ODE trajectory, DMD minimizes a KL divergence between the noised fake distribution and the noised real distribution:
The important observation is that the gradient of this KL objective can be expressed using score functions:
Here, the real score and fake score tell the generator how the fake distribution should move relative to the real distribution. After training, sampling is simply a single generator forward pass:
Limitation#
-
Not self-contained. DMD requires a pretrained diffusion model to provide the score signal, and the one-step generator also needs a reasonably good initialization.
-
Heavy overhead before training. The method requires extra data-generation work, such as constructing paired noise-image data for distillation.
Comparing One-step Methods#
| Method | Objective Type | ODE Dep. | Self-Contained |
|---|---|---|---|
| Diffusion Models | Regression | — | Yes |
| Consistency Models | Consistency constraint | Yes | Partial |
| CTM | Consistency constraint | Yes | Partial |
| MeanFlow | Regression (velocity) | Yes | Yes |
| DMD | Regression (KL-divergence) | No | No |
One thing I want to highlight from this table is the objective type. Consistency-based objectives are elegant, but the supervision is indirect: the model is asked to make two paths or two time points agree. Regression-style objectives are often easier to reason about and can be more stable in practice because they provide a more explicit target. This is somewhat orthogonal to the main topic of one-step generation, but it matters when comparing these methods as training recipes.
This is one reason MeanFlow and DMD are interesting in this list. MeanFlow turns flow learning into regression on an average velocity, while DMD turns distribution matching into a score-based regression signal. They are not free of assumptions, but their objectives are closer to direct regression than pure consistency constraints.
The remaining question is then not simply “can we generate in one step?” These methods already show several ways to do that. The more useful question is what kind of training signal makes one-step generation stable, self-contained, and less dependent on an inference-time trajectory or a pretrained diffusion teacher.
Drifting Models#
Training-Time Distribution Evolution#
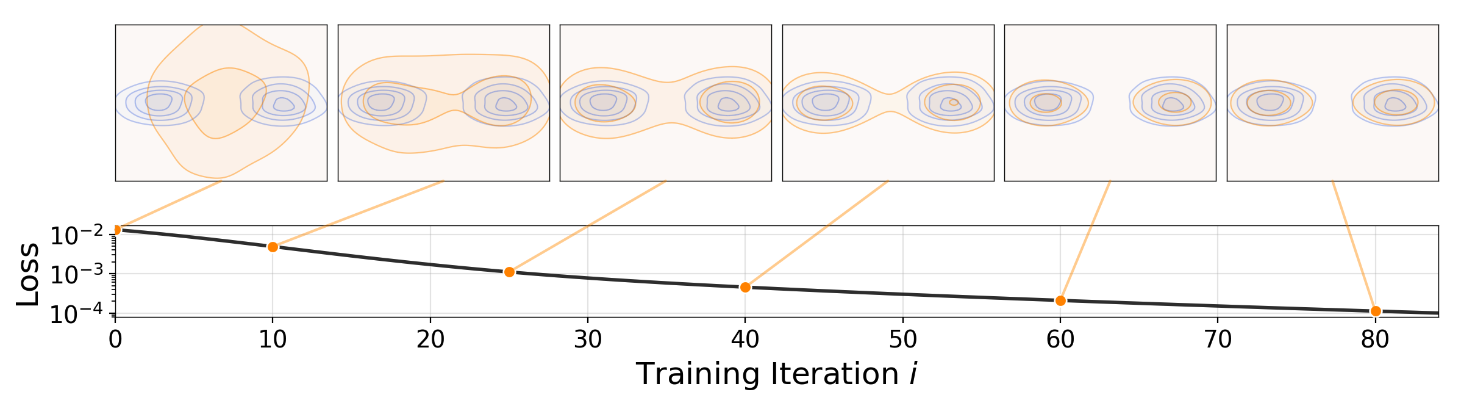
Drifting Models take a different perspective on where the generative dynamics happen. In diffusion and flow models, the generated distribution evolves along pseudo-time while sampling. In Drifting Models, the generated distribution evolves during training.
 |
|---|
| Drifting Models shift the distribution evolution from inference-time sampling to training-time updates. |
Method#
Drift#
Suppose the generator at training step
is the sample’s training-induced movement, which is why the method is called “drifting.” Since parameter updates already move generated samples during training, Drifting Models make this movement explicit and govern it with a drift field
Drift Field#
The drift field
If
Training Objective#
The training objective is derived from the fixed-point relation at equilibrium:
Drifting Models turn this relation into a stop-gradient regression target:
The important part is the dependence on
Drifting Field Design#
The drift field is built from an attraction-repulsion interaction. For a generated point
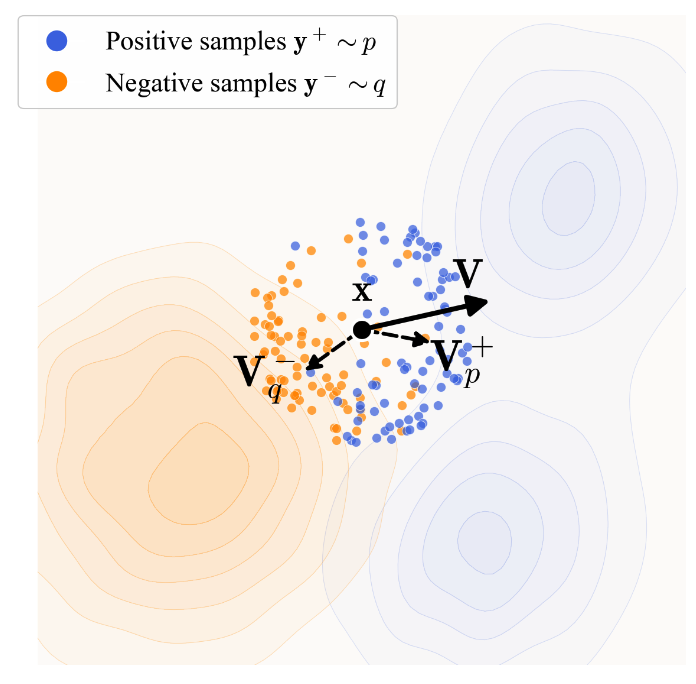
Formally, the drifting field is defined as
This construction satisfies the anti-symmetry condition
Implementation Details#
Two practical details matter for applying the drift objective to image generation: feature-space drift and CFG-conditioned sampling.
Encoder-Based Drift#
Doing the attraction-repulsion computation directly in raw pixel space is not enough. Pixel distances do not capture semantic similarity well in high-dimensional image domains, so the practical version computes similarity in feature space using a frozen self-supervised encoder
The generator can still output pixels or latents, and the encoder is used only during training to construct the drift target. At inference time, the encoder is not evaluated. This is why I would describe Drifting Models as not ODE-dependent, but not completely assumption-free: they remove the diffusion teacher and inference-time trajectory, but introduce a strong dependence on representation and kernel design.
Classifier-Free Guidance#
For conditional generation, CFG is introduced by changing how the positive and negative samples are drawn:
So CFG is not applied by mixing two predictions at every denoising step, as in diffusion sampling. It is learned during training and exposed as an input to the one-step generator.
Results#
Importance of Anti-Symmetry#
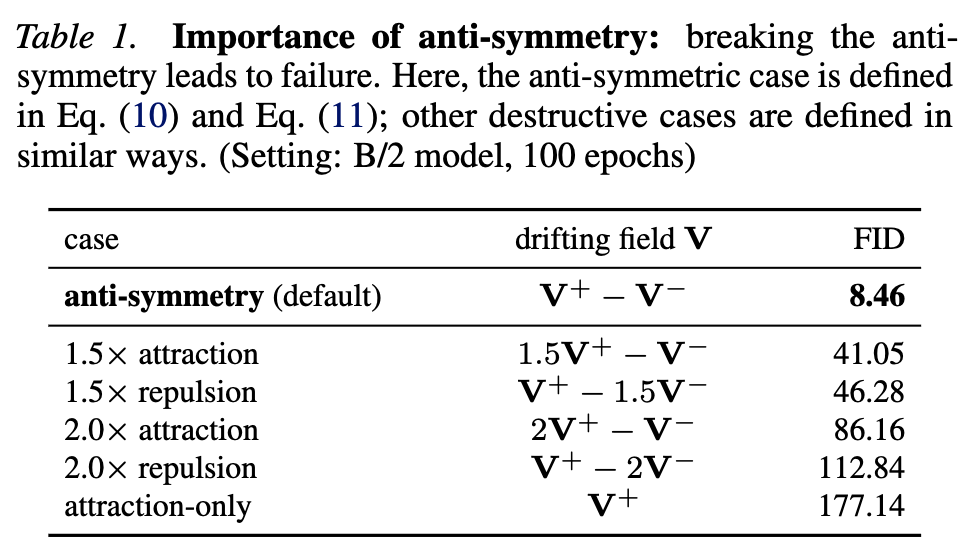
The anti-symmetric attraction-repulsion structure is not cosmetic. When the balance is broken, FID degrades sharply, which suggests that the field design is central to the method.
 |
|---|
| Breaking the anti-symmetric attraction-repulsion design substantially degrades FID. |
Ablations on Encoders#
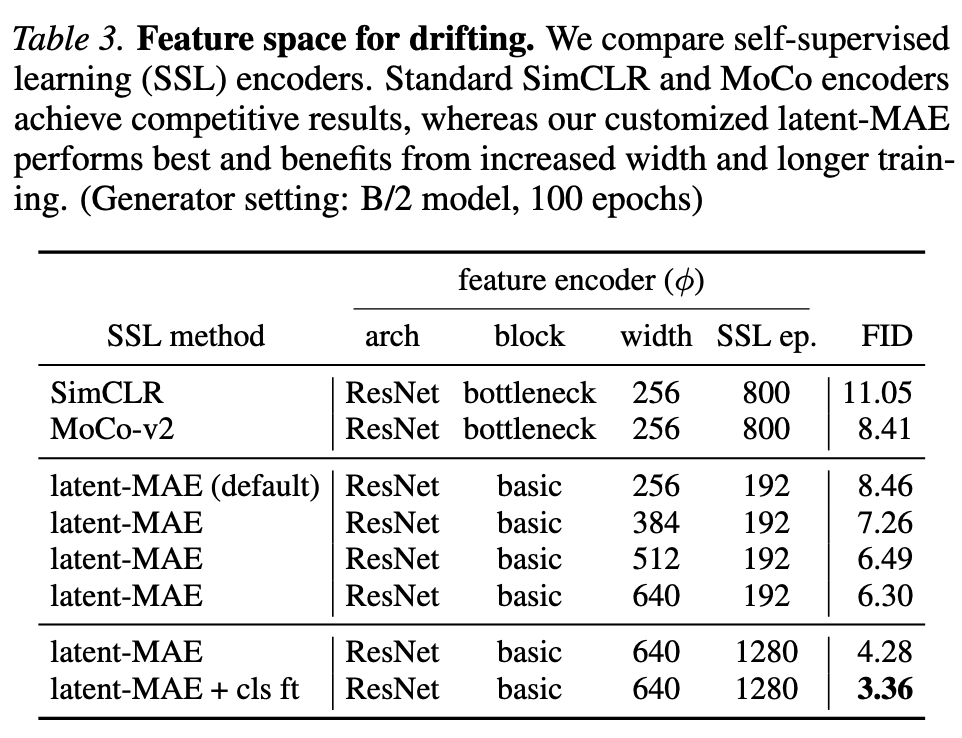
The feature encoder is another major factor. The ablation shows that representation choice has a large effect on FID, reinforcing that Drifting Models depend strongly on the feature space used to compute the kernel.
 |
|---|
| The feature encoder choice is a major part of the method’s empirical behavior. |
Limitation#
-
Theoretical gap. A vanishing drift field,
-
Kernel and representation dependency. The field is computed through
, so performance depends heavily on the encoder and kernel design. -
Design optimality is not guaranteed. The kernel, drifting field, and architecture are still design choices with room for improvement.
-
Scalability is still unverified. The presented setting does not yet cover generation beyond
Positioning#
| Method | Objective Type | ODE Dep. | Self-Contained |
|---|---|---|---|
| Diffusion Models | Regression | — | Yes |
| Consistency Models | Consistency constraint | Yes | Partial |
| CTM | Consistency constraint | Yes | Partial |
| MeanFlow | Regression (velocity) | Yes | Yes |
| DMD | Regression (KL-divergence) | No | No |
| Drifting Models | Regression (drift) | No | Partial |
References#
- Luhman and Luhman, Knowledge Distillation in Iterative Generative Models for Improved Sampling Speed (2021).
- Salimans and Ho, Progressive Distillation for Fast Sampling of Diffusion Models (ICLR 2022).
- Song et al., Consistency Models (ICML 2023).
- Kim et al., Consistency Trajectory Models: Learning Probability Flow ODE Trajectory of Diffusion (ICLR 2024).
- Geng et al., Mean Flows for One-Step Generative Modeling (NeurIPS 2025).
- Yin et al., One-step Diffusion with Distribution Matching Distillation (CVPR 2024).
- Deng et al., Generative Modeling via Drifting (arXiv:2602.04770).